AI-powered vaultless tokenization
Tokenize once, protect everywhere.
SecureToken Vaultless Tokenization finds every name, number and address in your data and tokenizes it the moment it appears. Your teams and agents work on a digital twin of production. No vault, no broken joins, no real values in AI.
The AI-Powered Tokenization Workflow
Find it. Tokenize it. Prove it.
Five steps run across every record, prompt and message, with evidence captured at each one.
Data Discovery
Discover the data.
SecureToken reads prompts, logs and messages the way a person would and marks exactly where each name, address and number starts and ends. Tables with no schema get the same read.
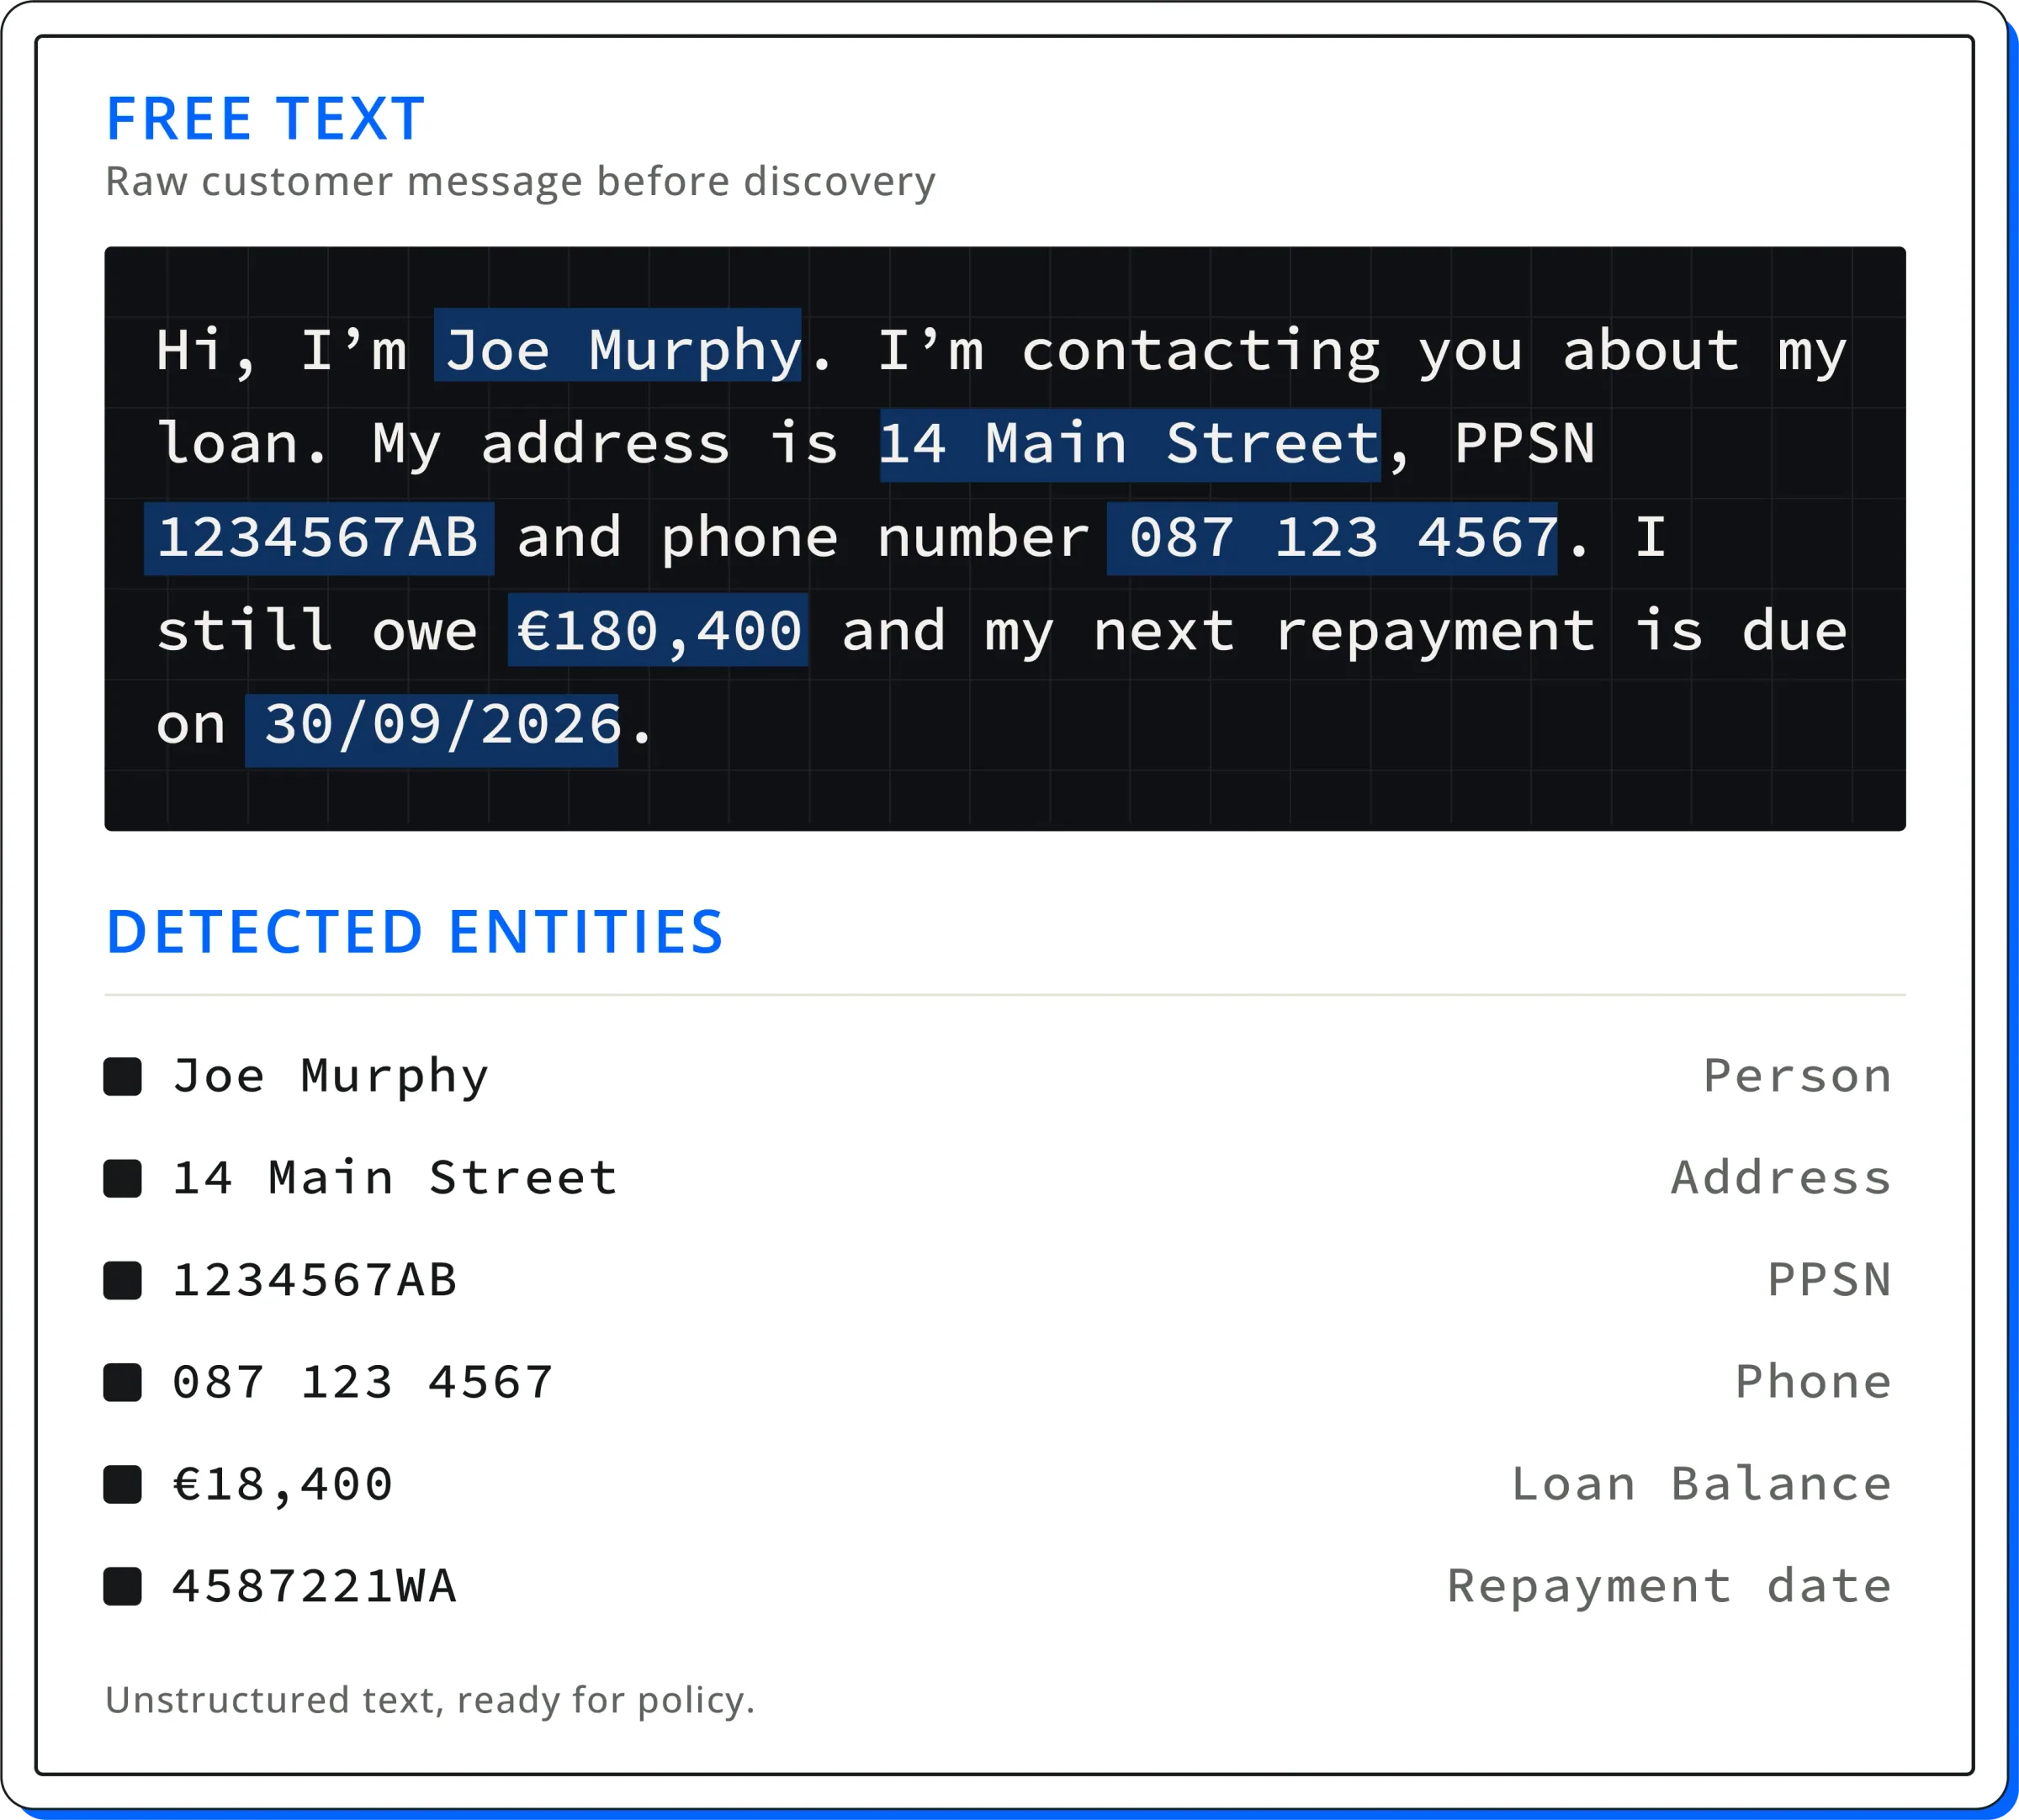
Data Protection
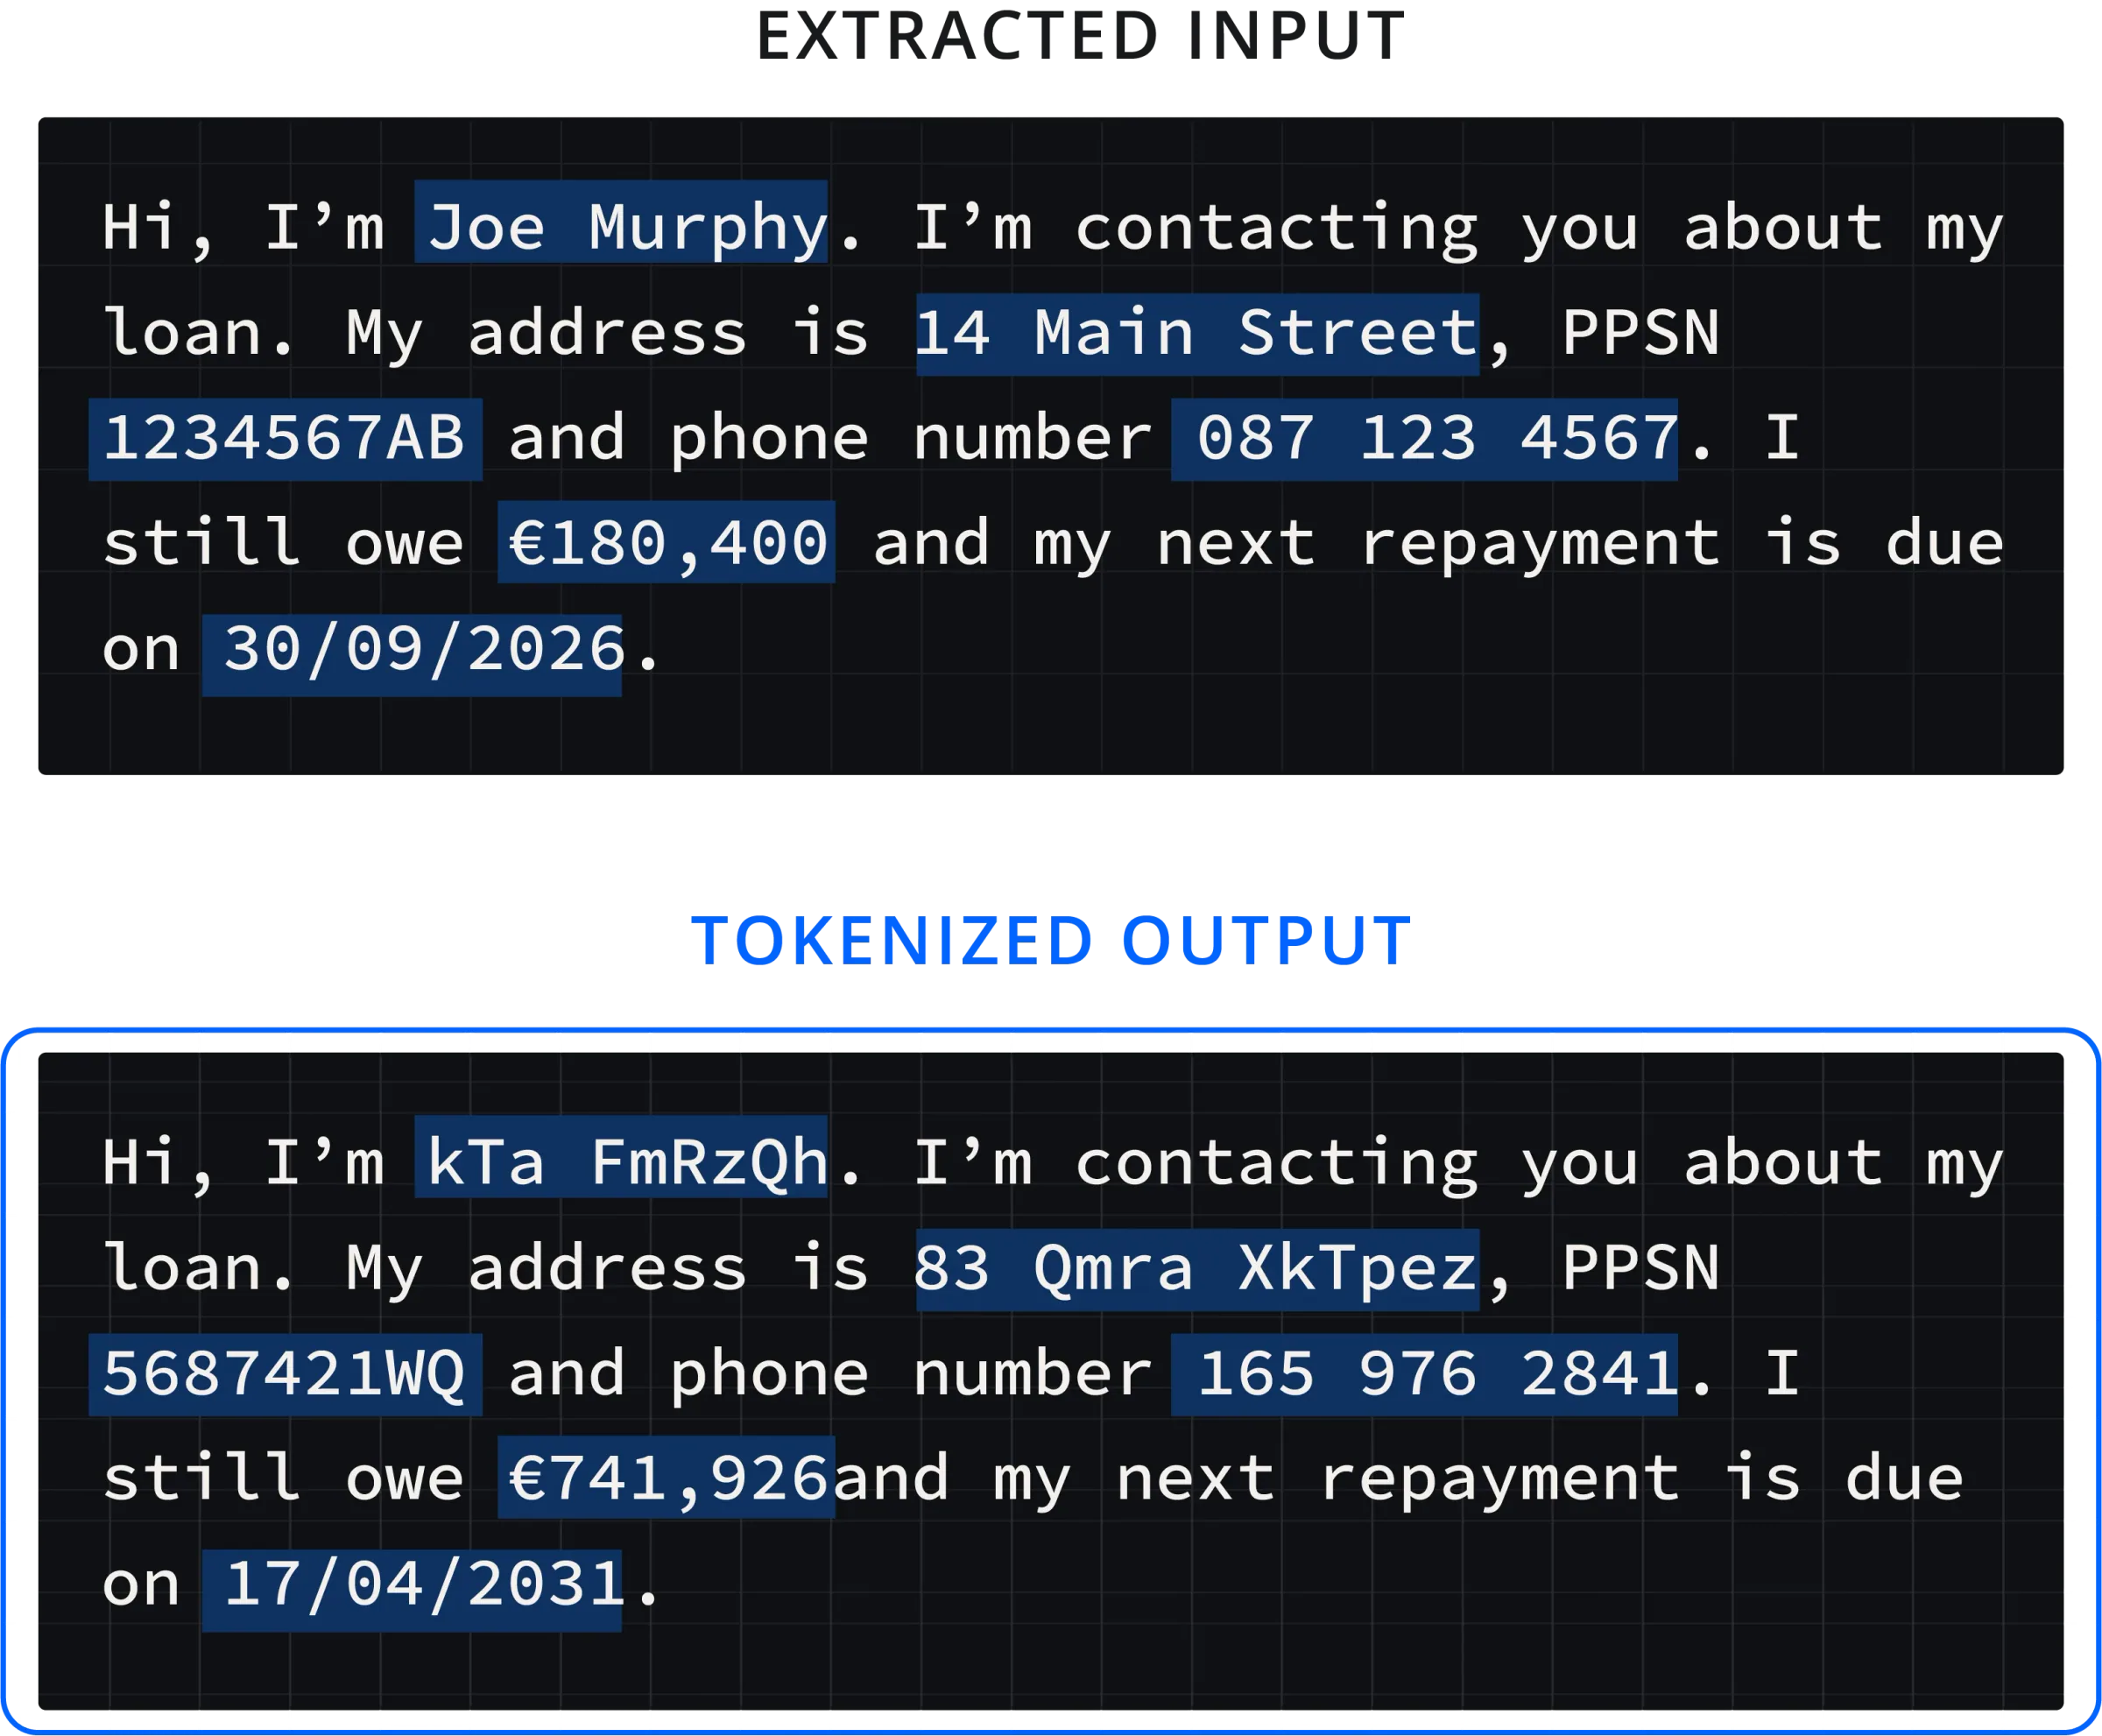
Tokenize inline.
The name becomes a token. The sentence around it stays as written, so every system downstream keeps running.
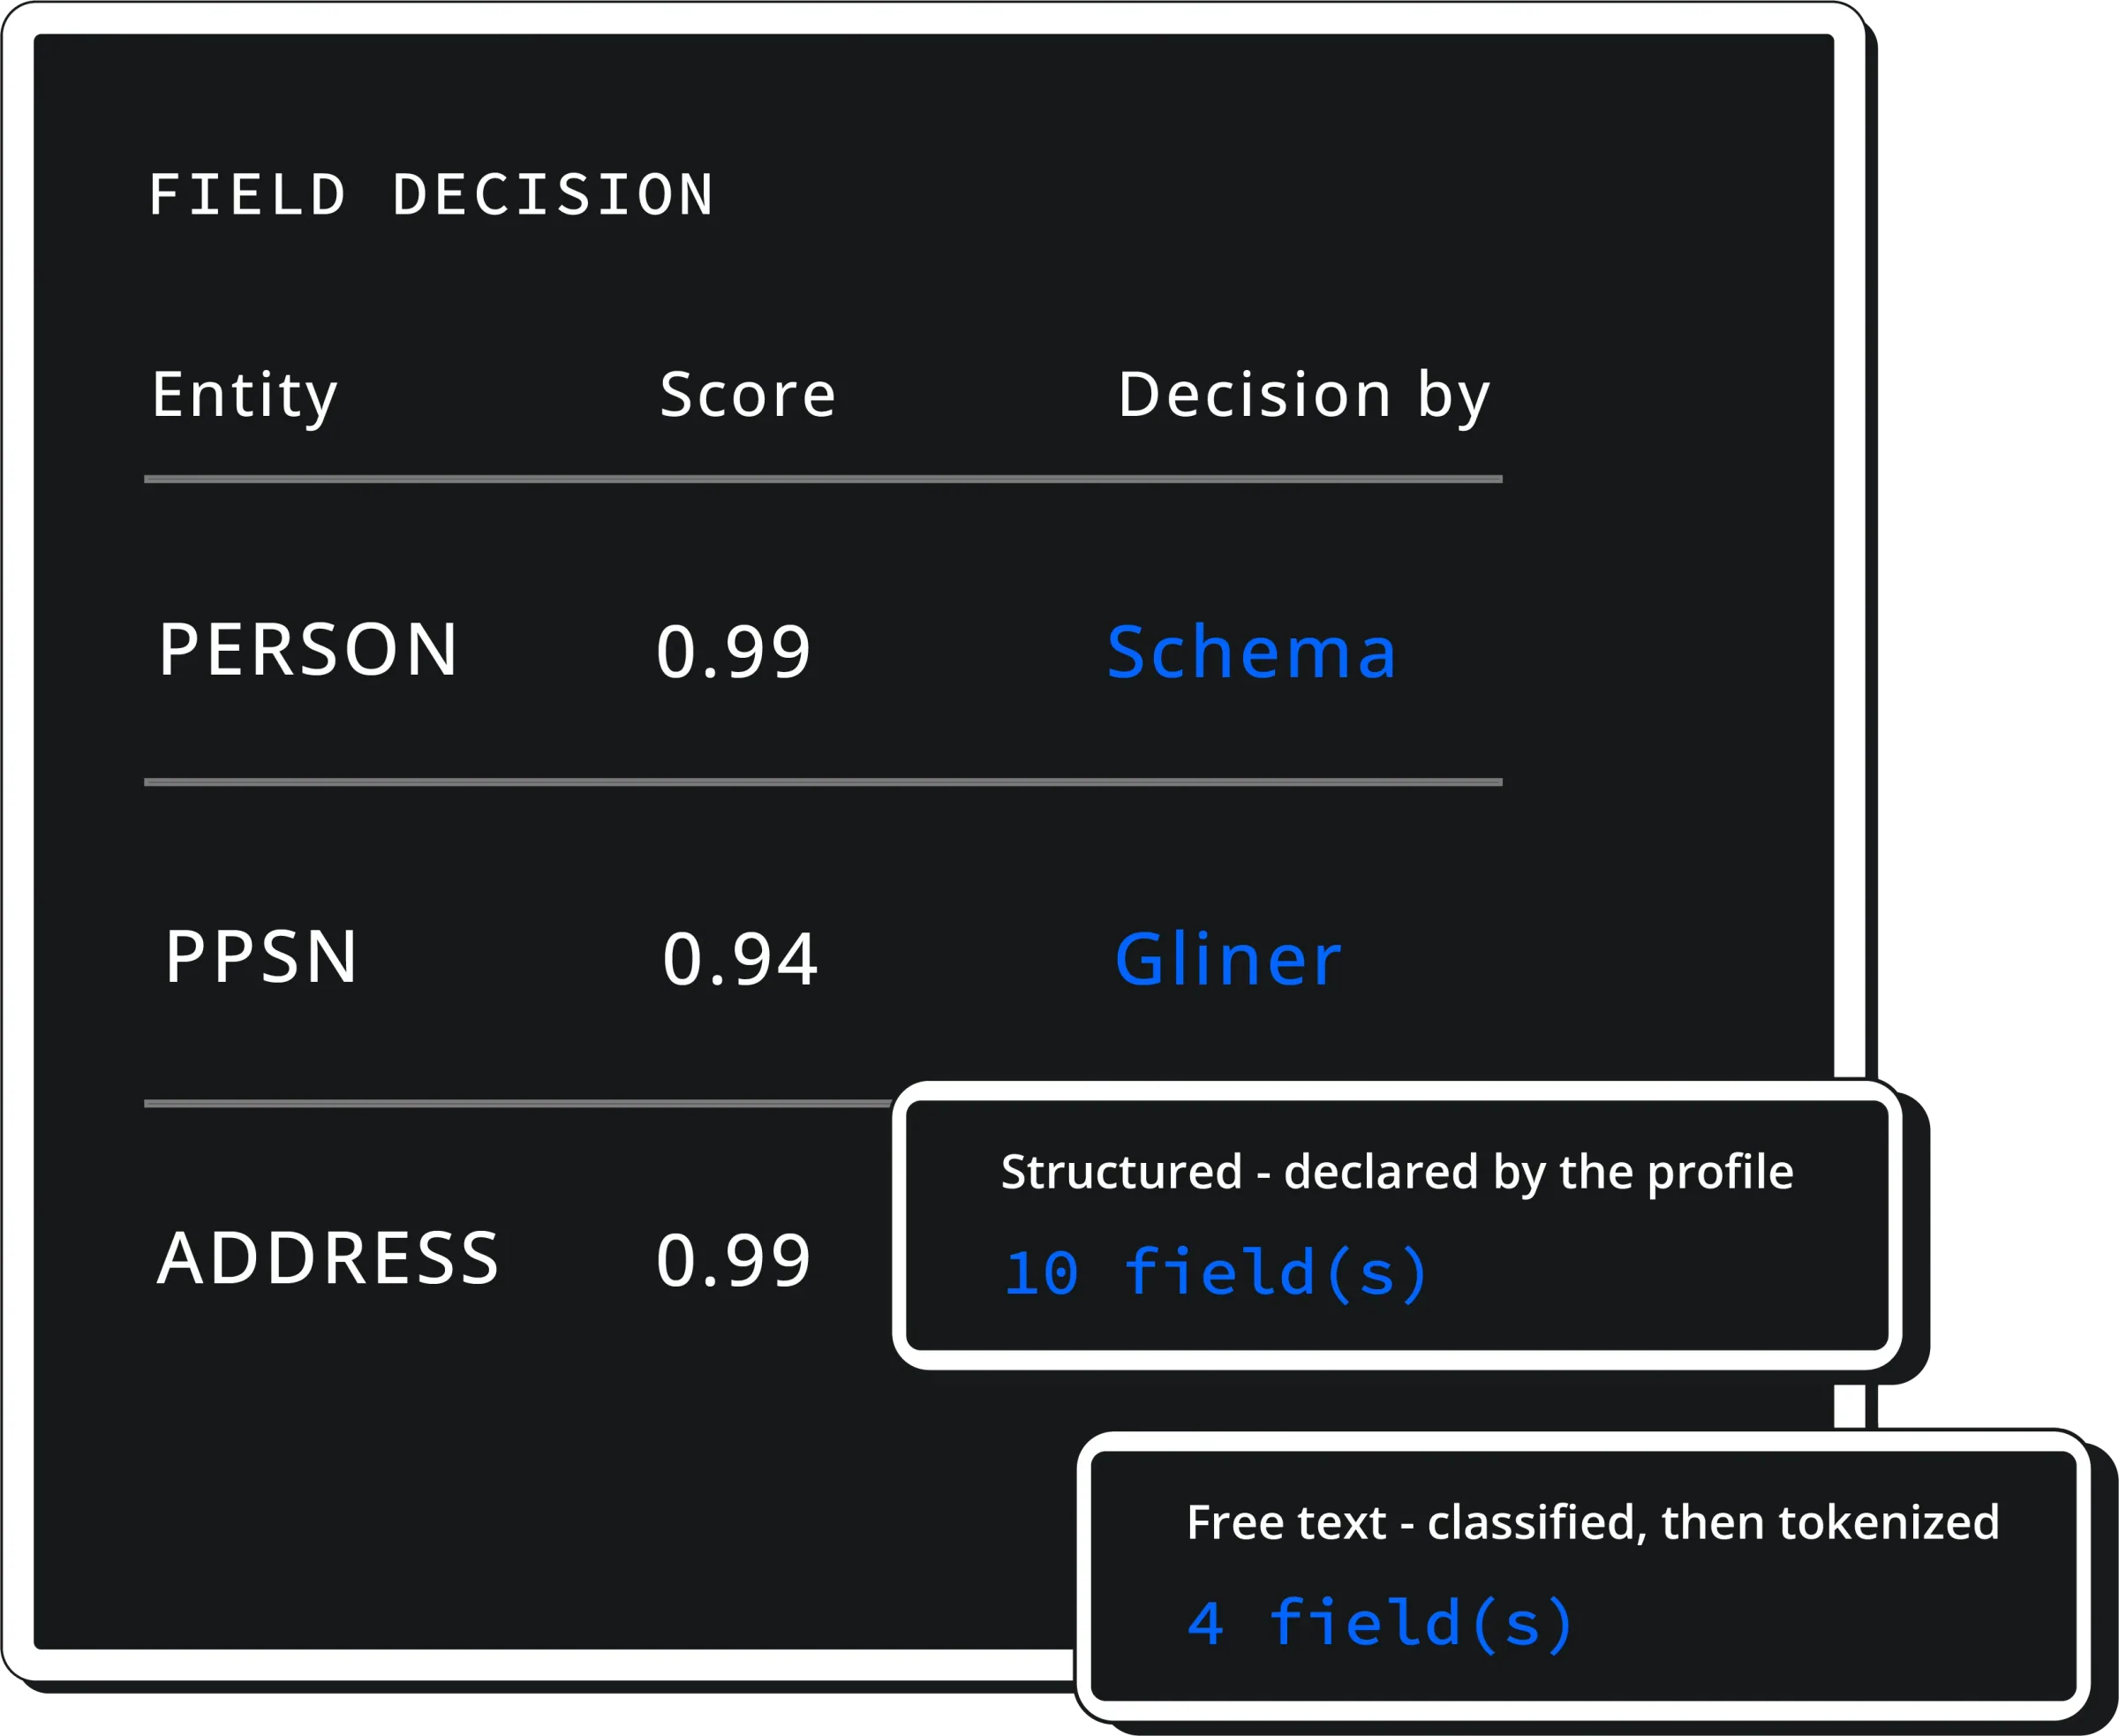
Policy Decisions
Decide in real time.
Each value carries a confidence score and the reason it was protected. The undocumented field, the Z-segment someone repurposed years ago: they all get swept anyway. Everything gets read.
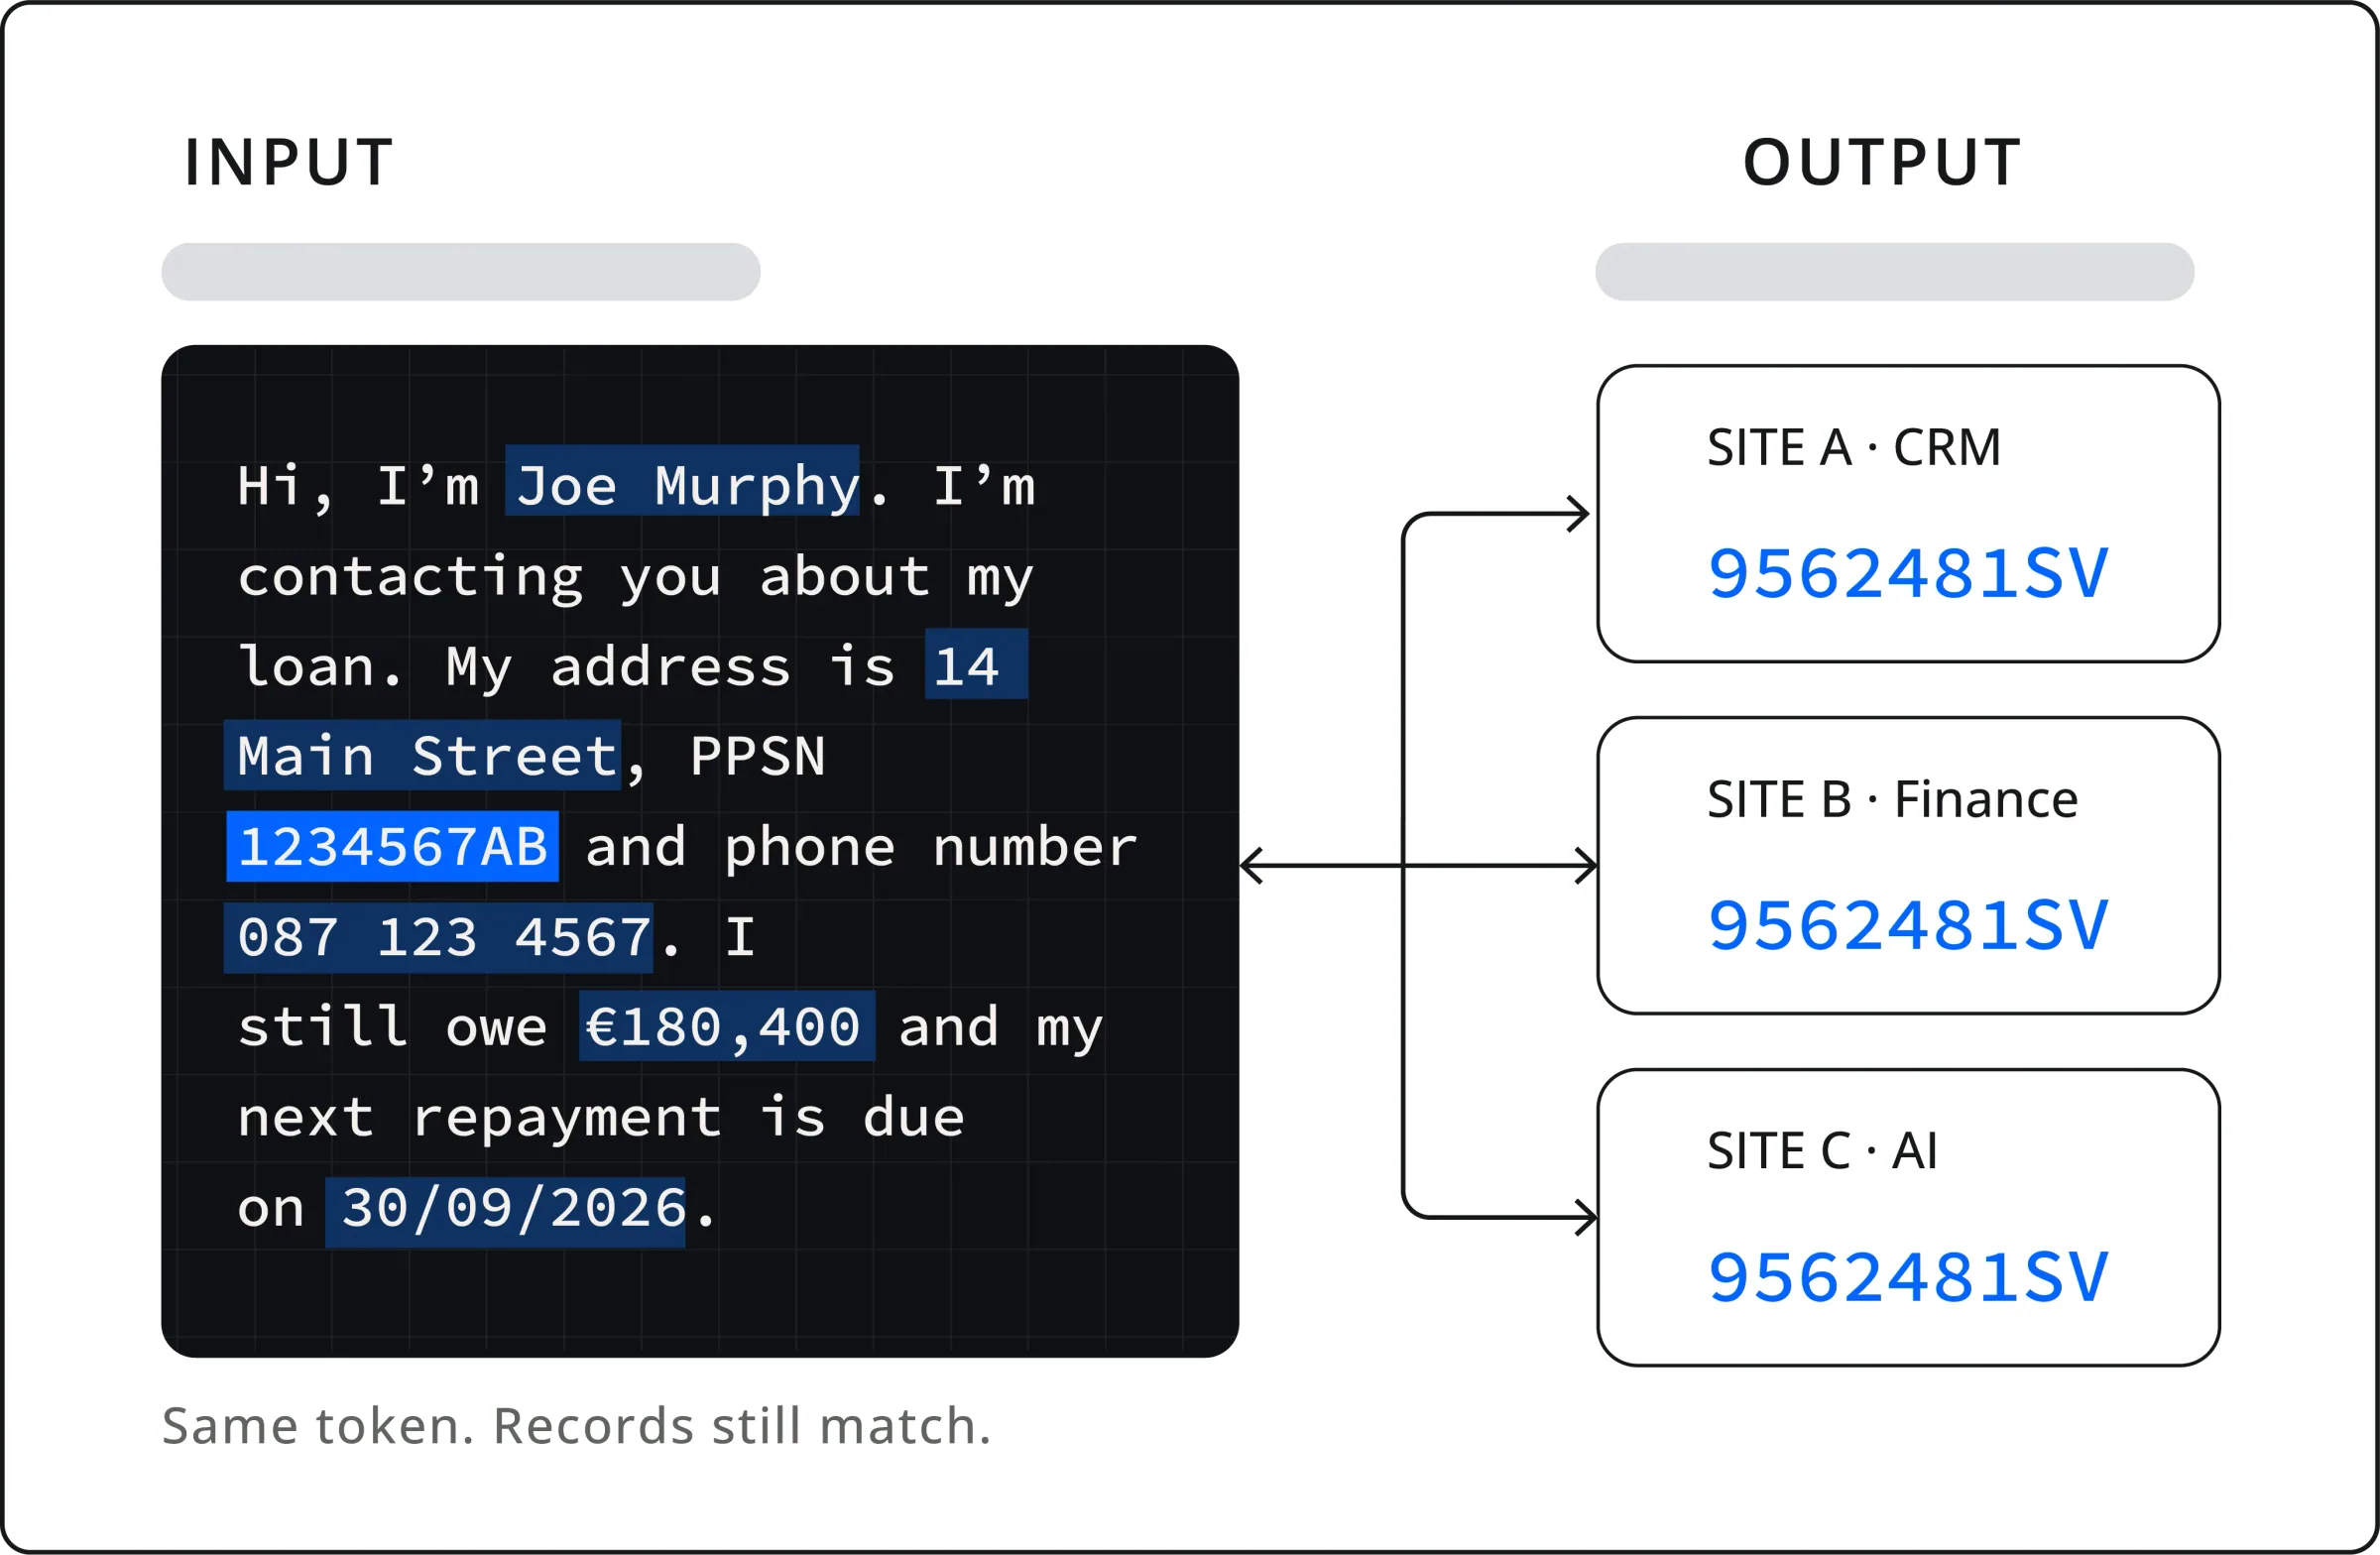
Deterministic Tokenization
Match everywhere.
Jane Murphy becomes the same token in the CRM, the ledger and the model. Records still match, joins still work, and nobody rebuilds a pipeline.
Safe Datasets
Use it anywhere.
Dev, test, analytics and AI get production-shaped records in the formats they expect. Real values stay in production.
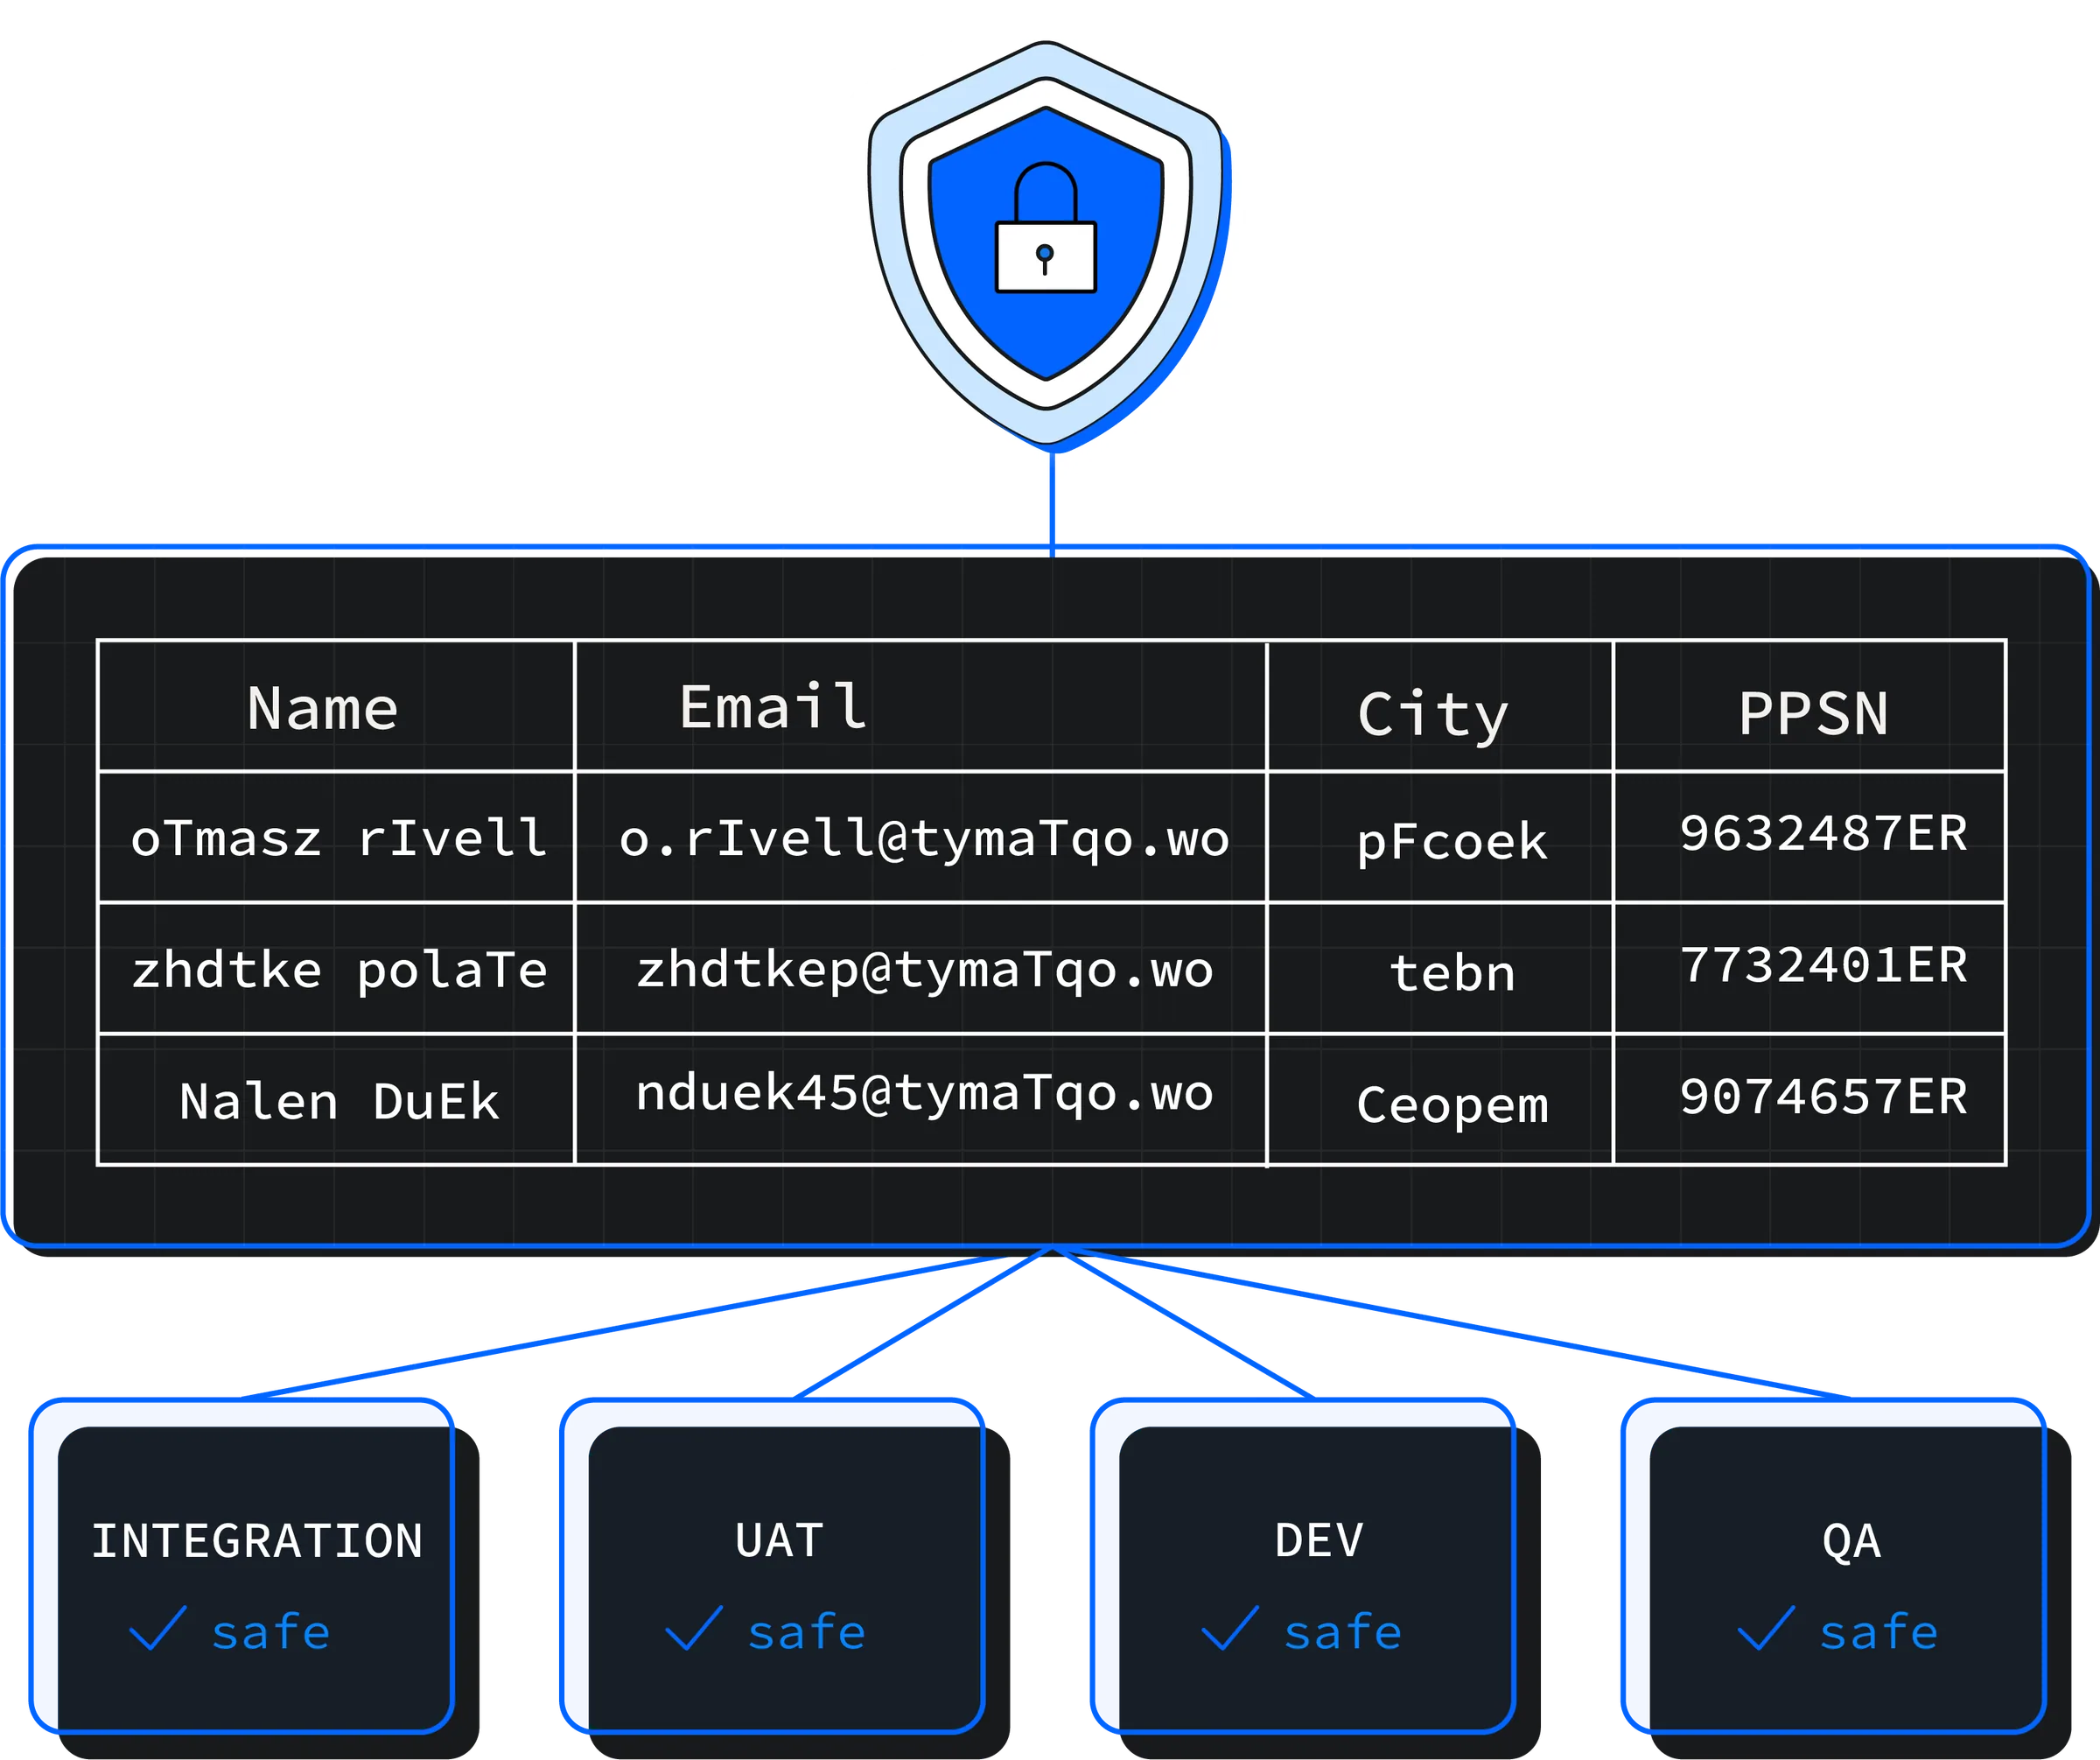
Production data, twinned.
A digital twin looks and behaves like production, so teams can build, test and analyse on realistic data while real values stay under policy.
Build AI on the twin
Train, fine-tune and run RAG on production-shaped records.
Analyse the twin
Joins, relationships and totals carry through, so analytics still reflect production.
Share the twin
Give partners and external teams usable data. Keep the real people behind it protected.
Refresh the twin
The same value returns the same token every time, so test cases and joins keep working.
See it on your own data.
Bring a sample table or prompt. We'll run discovery and tokenization live.
Why Bluemetrix SecureToken
A compliant digital twin for your data
Comparison of SecureToken with TDM alone
SecureToken
Discovery + tokenization + policy
TDM alone
Subset, mask, provision
SecureToken
Discovery + tokenization + policy
TDM alone
Subset, mask, provision
Use cases
Tokenized wherever you work.
Digital twin for dev & test
Give developers production-shaped data for dev, test and UAT while real values stay in production.
Learn moreSecure AI Agents
Let agents and models work on tokenized values from prompt to output, releasing real values only when policy allows.
Learn moreHybrid AI Deployment
Apply the same tokenization and policy across cloud, private data centres and isolated environments.
Learn moreHL7/FHIR Interoperability
Protect identifiers inside HL7 messages and FHIR resources while preserving the formats downstream systems expect.
Learn moreCloud Migration
Tokenize regulated values as data moves between legacy systems, cloud platforms and modern data estates.
Learn moreData Sovereignty
Keep original values in the environment and jurisdiction you choose, with recovery governed by policy.
Learn moreFAQ
AI-Powered Vaultless Tokenization questions
What is a tokenized digital twin?
It is a copy of production where every personal value has been replaced with a token. The tables, formats and relationships match the original, so a customer ID that joins three systems in production joins the same three systems in the twin. Developers test against it, analysts report on it and models train on it as they would on production. The difference is exposure: if the twin leaks, the attacker gets tokens and nothing they can use.
What is AI-powered vaultless tokenization?
Traditional tokenization stores every real value in a central vault and looks it up on every call. That vault becomes the most valuable target in the estate, and every lookup adds latency. SecureToken generates each token by algorithm, so no store of real values exists. AI models find the personal data first, across tables, files and free text, and each value then becomes a format-preserving token. A 10-digit phone number stays a 10-digit number, and every system that reads it keeps working.
Can authorised users still see the underlying data?
Yes. Tokenization is reversible by policy. When a fraud analyst needs the real customer name behind a flagged transaction, policy checks who they are and why they are asking, then releases that value for that purpose. A developer making the same request against the same record gets the token. Every release is logged with the person, the value and the reason, so you can show an auditor exactly who saw what.
Does it work on free text and AI prompts?
Yes, and this is where pattern-based tools fall short. A rule catches a phone number in a phone column, but personal data in a support ticket, a log line or an HL7 Z-segment rarely sits in a labelled field. SecureToken's detection ensemble reads the text in context, marks the exact boundaries of each name, address and identifier, and tokenizes it in place. The prompt reaches the model with its meaning intact and its personal data replaced.
How is it different from masking or other AI guardrails?
Masking replaces values for good, so the data loses its value for joins, testing and analytics. Guardrails sit around the agent and try to stop it doing the wrong thing, which depends on predicting every bad prompt. SecureToken changes the data itself. The agent works on tokens from start to finish, so even a prompt injection that succeeds returns tokens. Others control the agent. We neutralise the data.
Which regulations does it help with?
GDPR, HIPAA, PCI DSS and DORA, among others. Each regulation applies to personal data wherever it lives, so every copy in dev, test or an AI pipeline adds to your scope. Tokenized data reduces that footprint: the twin in your test environment holds tokens, and the real values stay in production. The audit trail then supplies the evidence each regulation asks for, from who accessed a value to why it was released.